 Xingxin on Bug
If you are a researcher using a Franka robot, you are not looking at the DROID just for fun. As DROID has become more popular, more versions and conversions have appeared, and they do not all use the data in the same way.
For example, do you know the differences among these🤔?
gs://gresearch/robotics/droidlerobot/droid_1.0.1- Isaac-GR00T DROID sample data
Many crucial details are hidden beneath the surface. To make sense of them, I will explain the dataset from the ground up while keeping the big picture in mind. Once the foundation is clear, your coding agent can handle the rest.
🧾 Cheat Sheet
This section is a TL;DR for quick reference. Once you understand the mechanics of DROID detailed below, this cheat sheet will be self-explanatory.
| Field | Observed range in the sample | Used by pi05_droid? |
|---|---|---|
observation/gripper_position | [0,1] | Yes, state index 7 (the eighth value) |
action_dict/gripper_position | [0,1] | Yes, action index 7 (the eighth value) |
action_dict/gripper_velocity | [-1,1] | No |
What is DROID and why should we care?
DROID is a massive real-world dataset collected on the Franka Panda robot via teleoperation. You can refer to the original DROID paper or gs://gresearch/robotics/droid for the exact number of episodes.
Because of its scale, many state-of-the-art VLA models offer fine-tuned checkpoints based entirely on this dataset. A few examples include:
- -
joint_velocity:gs://openpi-assets/checkpoints/pi05_droid, as listed in the OpenPI DROID guide. - -
joint_position:gs://openpi-assets/checkpoints/pi05_droid_jointpos, as introduced by 📄PolaRiS: Scalable Real-to-Sim Evaluations for Generalist Robot Policies. nvidia/GR00T-N1.7-DROID.allenai/MolmoAct2-DROID.
If you believe in pretraining robotics foundation models similarly to LLMs, you should seriously consider leveraging these checkpoints.
Different Sources of DROID
📌Official DROID
The official DROID release is hosted in a Google Cloud bucket. This post focuses on the 📄RLDS: an Ecosystem to Generate, Share and Use Datasets in Reinforcement Learning release at gs://gresearch/robotics/droid/1.0.1.
RemarkDROID also provides raw recordings with higher-resolution and stereo camera data. RLDS is not its only official format. See the dataset documentation.
📌 LeRobot port
LeRobot is a robot learning framework with its own data format, LeRobotDataset. The lerobot/droid_1.0.1 dataset is a conversion of the RLDS release. Its keys and storage layout differ from the original.
📌 Isaac GR00T demo data
The original RLDS data represents orientations in SO(3) using Euler angles. GR00T’s DROID example uses Rot6D (first 2 rows of the rotation matrix) to represent rotation.
TipIt turns out
Rot6Dis easier for neural network to learn. See more at 📄On the Continuity of Rotation Representations in Neural Networks.
RemarkOne more tiny detail about the frame representation in GR00T: by the release of N1.7, the rotation stored in the demo data is obtained by right-multiplying the DROID rotation by the change-of-basis matrix :
where is
In short, GR00T N 1.7 was pre-trained on top of a lot egocentric data, which is why they apply this transformation. See more at sample conversion script and orientation conversion script.
The Hardware and Its Setup
First, let’s look at the DROID hardware setup.
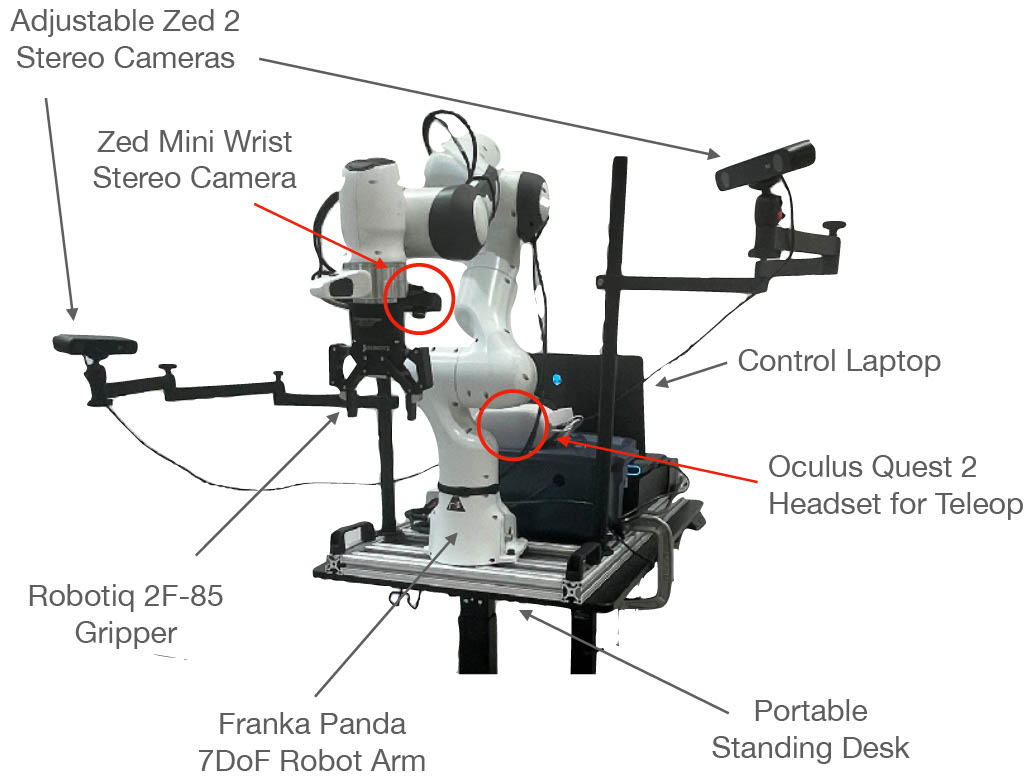
© DROID team
- Robot: Franka Emika Panda, represented by
ferin franka_description. - Cameras: two ZED 2 cameras for external views and one ZED Mini for the wrist view.
- Gripper: Robotiq 2F-85.
- Teleoperation device: Oculus Quest 2.
Can my Franka use the DROID dataset?There are several Franka models in franka_description. If mine is an
fr3, can I still use DROID?DROID can be useful across these robots, but similar arm geometry does not guarantee identical behavior.
- 😁Good news: all the Franka robots share the same DH parameters.
- 😕Bad news:
fr3has significantly different joint limits compared to theferused in DROID.Intuitively, it seems that joint space is harder to generalize across models, while Cartesian space might be easier. I will leave you to ponder that!
Overview of the Observation and Action Spaces
For robot learning, this is one of the most important⭐️ parts to understand. The released dataset includes a features.json file that defines its fields.
RemarkThe collection loop targets 15 Hz. The RLDS sample contains 3 RGB views with shape
(180, 320, 3): height, width, and channels. These are the released image dimensions, not the cameras’ native resolution.
📌 Observation space: observation/*
| Key | Shape | Dtype | Description |
|---|---|---|---|
wrist_image_left | (180, 320, 3) | uint8 | Wrist camera’s left stereo view |
exterior_image_1_left | (180, 320, 3) | uint8 | First external camera’s left stereo view |
exterior_image_2_left | (180, 320, 3) | uint8 | Second external camera’s left stereo view |
cartesian_position | (6,) | float64 | Flange pose: [x, y, z, roll, pitch, yaw], in meters and radians |
joint_position | (7,) | float64 | 7 Franka joint angles, in radians |
gripper_position | (1,) | float64 | Gripper closedness: 0 = open, 1 = closed |
📌 Action space: action_dict/*
| Key | Shape | Dtype | Range or units | Description |
|---|---|---|---|---|
cartesian_velocity | (6,) | float64 | Normalized; nominally | Translation and rotation commands |
cartesian_position | (6,) | float64 | Meters and radians | Cartesian pose target |
joint_velocity | (7,) | float64 | Normalized; nominally | Joint commands |
joint_position | (7,) | float64 | Radians | Joint position targets |
gripper_position | (1,) | float64 | [0,1] | Gripper closedness target |
gripper_velocity | (1,) | float64 | [-1,1] in the teleoperation path | Normalized gripper command |
TipFeel overwhelmed😵💫? No worries, we will break down exactly how these are generated later.
Observation versus stateLeRobot separates proprioceptive values under
observation.statefrom camera inputs underobservation.images. These names are useful, butobservation.statedoes not necessarily contain the full dynamical state. For example, joint positions alone omit joint velocities.See more at the Section 17.3 of Reinforcement Learning: An Introduction about the discussion between state and observation.
The observation.images Fields
Let’s look at the camera signals first, as they provide the most intuitive understanding of the system. There are 3 cameras in total: 2 third-person views and 1 wrist view.
Defining the “Left”
We must be clear about what “left” means in the dataset schema. The schema includes:
exterior_image_1_leftexterior_image_2_leftwrist_image_left
It is a common pitfall to assume “left” means the camera is positioned on the left side of the robot’s base frame. Instead, “left” refers exclusively to the left lens of the Zed camera, which serves as the canonical camera feed.

A ZED camera has two lenses.
How Policies Use the Camera Views
Because DROID provides 3 camera views, you might assume all VLA models use all of them. The reality is a bit more complex😵💫.
RemarkBelow, I refer to
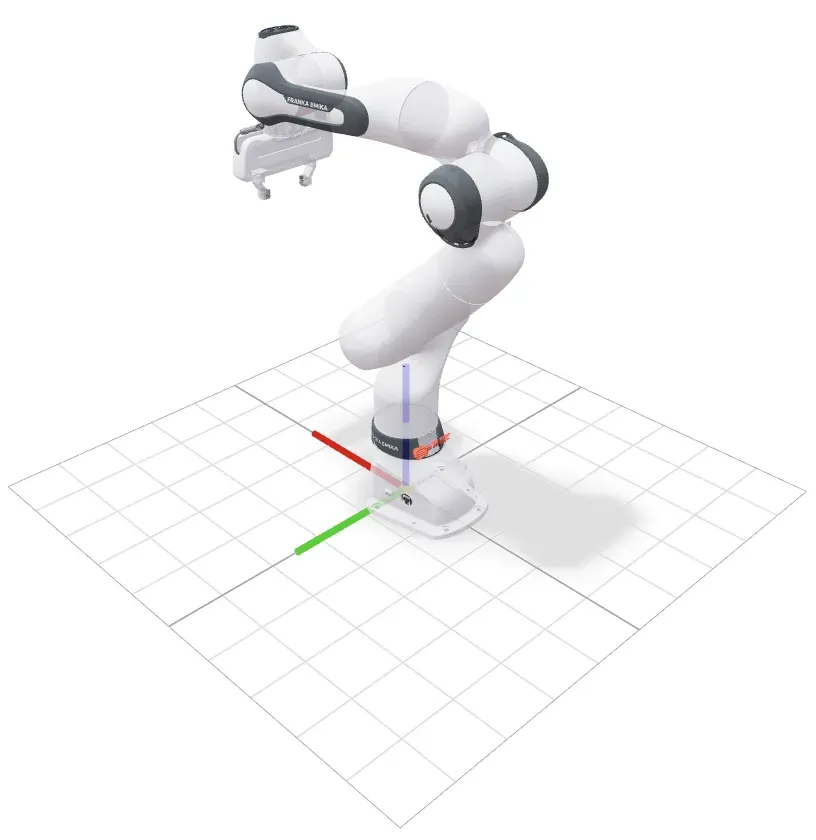
exterior_1as the left-hand side camera andexterior_2as the right-hand side camera relative to the robot base frame.In the robot base frame, the left side has and the right side has .
- axis is red
- axis is green
- axis is blue
📌 OpenPI -DROID
In its fine-tuning config, only allocates slots for 2 camera views (one wrist, one exterior). However, it does not permanently drop either the left or right third-person camera.
During training, OpenPI randomly chooses between the left and right exterior cameras and feeds it into the policy’s single third-person input slot. The policy learns from both viewpoints but only processes one at a time. During inference, the operator must explicitly choose to roll out with either the left or right camera. See droid_rlds_dataset.py.
📌 NVIDIA GR00T N1.7-DROID
Conversely, nvidia/GR00T-N1.7-DROID explicitly drops the right-hand side exterior_2_left camera and only includes the left-hand side camera in its fine-tuning script.
📌 MolmoAct2-DROID
The final approach uses everything. The observation space for allenai/MolmoAct2-DROID includes all 3 cameras during both training and inference.
These examples show why we need to check a checkpoint’s actual inputs🔎, even when all 3 checkpoints are described as “DROID models”.
Observation: Proprioception
Within the LeRobot context, proprioceptive data is stored under observation.state. It consists of:
| Key | Shape | Dtype | Description |
|---|---|---|---|
cartesian_position | (6,) | float64 | Flange frame: [x, y, z, roll, pitch, yaw] |
joint_position | (7,) | float64 | 7 Franka joint angles |
gripper_position | (1,) | float64 | Gripper closedness: 0 = open, 1 = closed |
📌 End-effector pose
In DROID, the end-effector frame is the Franka flange frame, panda_link8. The Polymetis robot configuration names this link explicitly, and DROID’s robot interface computes its pose using forward kinematics.
In robotics, we often set the tool frame directly between the two gripper fingers as the end-effector frame. DROID, however, uses the flange frame, even with a Robotiq gripper attached.
Warning⚠️ This is a critical detail! If your embodiment uses a different gripper, such as the Franka Hand, the UMI setup, or a generalist-style gripper, you must remember that DROID data is tracked at the flange frame. Understanding this ensures smoother transfer to your specific hardware.
Given this context, cartesian_position records the flange frame’s SE(3) pose measured in the robot’s base frame, with the rotation component represented as Euler angles.
RemarkMore precisely, the Euler angles refer to X-Y-Z fixed angles(extrinsic Euler). See the conversion helpers, which uses SciPy’s lowercase
xyzconvention: extrinsic rotations about fixed axes.
📌 Joint position
This value simply records the joint states of the 7 joints of the Franka robot. ⚠️ Be aware that the joint space limits of the Franka Panda and the Franka Research 3 differ slightly, which is reflected in the dataset’s statistical bounds.
📌 Gripper position
This is a normalized value in [0,1].
If is the measured opening width and is the configured maximum width, the robot interface computes
Thus, means fully open (max width: 85mm for Robotiq 2F-85, 80mm for Franka Hand), and means fully closed.
Teleoperation
We have now covered the main observation fields. Before discussing the action fields in detail, let’s walk through DROID’s teleoperation process.
The big picture is: As the operator moves an Oculus Quest 2 controller, the DROID continuously controls the robot’s flange frame. It compares the controller’s motion (since a reference snapshot) with the robot’s motion (since its own snapshot), then commands the robot to reduce the gap.
RemarkThe equations below describe the default Cartesian velocity teleoperation path. The gain and step-size constants are implementation settings, not universal properties of every DROID recording. The repository’s version records show that earlier collection code used different values.
Notation
Inspired by Russ Tedrake and Introduction to Robotics: Mechanics and Control, I will define the notation first, then apply it to the DROID pipeline.
📌 Position vector:
denotes a position vector. A position requires a reference point and axes. We write:
which reads as “the position of point , measured from point , with components expressed in frame ‘s basis.”
📌 Omitting the subscript
When the “measured from” and “expressed in” frames are identical, we drop the subscript. Every position in this pipeline is expressed in the same frame it is measured from.
📌 Orientation: ; pose:
denotes rotation: is the orientation of frame measured from frame . denotes a rigid transformation (a pose), which packages both:
RemarkConcretely, is a homogeneous transformation matrix: is the top-left block, and is the first 3 entries of the 4th column.
📌 Symbols in DROID teleoperation pipeline
Let:
- denote the control-step index.
- denote the stationary Franka robot base frame (the world frame).
- denote the end-effector (flange) frame.
- denote the Oculus controller frame.
- denote the measured joint positions and velocities.
- denote measured gripper closedness.
- denote the pose of measured from .
Applying the decomposition to the end-effector gives:
For an ideal rigid arm with a fixed base, its mechanical state can be written as
RemarkTo connect this to hardware, you can read these directly from libfranka: C++ library for Franka Robotics research robots:
- corresponds to
std::array franka::RobotState::q- corresponds to
std::array franka::RobotState::dq
The flange pose is determined by forward kinematics:
Check the end-effector frame in libfranka
RobotState::O_T_EEis the pose of configured end-effector frame in Desk, which need not be the flange. ItsF_T_EEfield describes the transform from flange to end effector. In matrix form, the flange pose isO_T_EEmultiplied by the inverse ofF_T_EE. DROID instead computes the pose of its configured model link from joint angles. See the libfranka field definitions.
O_T_EEreads as “origin to end-effector”.F_T_EEreads as “flange to end-effector”TODO: add a diagram of Franka Desk
The proprioceptive part of the released RLDS observation
| Key | Shape |
|---|---|
joint_position | (7,) |
cartesian_position | (6,) |
gripper_position | (1,) |
can therefore be written as
Defining the Control Boundaries
In control theory, we often write for “the” control input. In robot learning, what we call an “action” depends entirely on where we draw the system boundary. Consider 3 distinct levels of control in this pipeline from top to bottom:
- The DROID conversion layer: The input is a processed teleoperation command.
- The low-level controllers: The input consists of absolute joint and gripper position targets .
- The physical arm: The input is joint torques .
The Journey of a Teleoperation Signal
One human motion, 4 recorded action spaces. After reading this section, you will understand how a single teleoperation signal cascades into all 4 kinds of action space that DROID records, in the order they are derived:
cartesian_velocitycartesian_positionjoint_velocityjoint_position
To spark your interest🥳, here are a few fun facts before we dive in.
- the
cartesian_velocityis the “root” of other actions since Oculus Quest 2 is a 6DoF controller. - the
cartesian_positionis a byproduct recorded alongside it and it is one of the two targets NVIDIA’s GR00T N1.7-DROID learns directly. - the
joint_velocityis the default finetuned action space by the famous . - the
joint_positionis featured in Physical Intelligence’s follow up work 📄PolaRiS: Scalable Real-to-Sim Evaluations for Generalist Robot Policies.
Sounds fun? Let’s trace the signal step by step!
%3btext-align:center%3b%7d%23mermaid-0 .edgeLabel p%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .edgeLabel rect%7bopacity:0.5%3bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bfill:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 .labelBkg%7bbackground-color:rgba(232%2c 232%2c 232%2c 0.5)%3b%7d%23mermaid-0 .cluster rect%7bfill:%23ffffde%3bstroke:%23aaaa33%3bstroke-width:1px%3b%7d%23mermaid-0 .cluster text%7bfill:%23333%3b%7d%23mermaid-0 .cluster span%7bcolor:%23333%3b%7d%23mermaid-0 div.mermaidTooltip%7bposition:absolute%3btext-align:center%3bmax-width:200px%3bpadding:2px%3bfont-family:arial%2csans-serif%3bfont-size:12px%3bbackground:hsl(80%2c 100%25%2c 96.2745098039%25)%3bborder:1px solid %23aaaa33%3bborder-radius:2px%3bpointer-events:none%3bz-index:100%3b%7d%23mermaid-0 .flowchartTitleText%7btext-anchor:middle%3bfont-size:18px%3bfill:%23333%3b%7d%23mermaid-0 rect.text%7bfill:none%3bstroke-width:0%3b%7d%23mermaid-0 .icon-shape%2c%23mermaid-0 .image-shape%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3btext-align:center%3b%7d%23mermaid-0 .icon-shape p%2c%23mermaid-0 .image-shape p%7bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bpadding:2px%3b%7d%23mermaid-0 .icon-shape rect%2c%23mermaid-0 .image-shape rect%7bopacity:0.5%3bbackground-color:rgba(232%2c232%2c232%2c 0.8)%3bfill:rgba(232%2c232%2c232%2c 0.8)%3b%7d%23mermaid-0 :root%7b--mermaid-font-family:arial%2csans-serif%3b%7d%3c/style%3e%3cg%3e%3cmarker orient='auto' markerHeight='8' markerWidth='8' markerUnits='userSpaceOnUse' refY='5' refX='5' viewBox='0 0 10 10' class='marker flowchart-v2' id='mermaid-0_flowchart-v2-pointEnd'%3e%3cpath style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b' class='arrowMarkerPath' d='M 0 0 L 10 5 L 0 10 z'/%3e%3c/marker%3e%3cmarker orient='auto' markerHeight='8' markerWidth='8' markerUnits='userSpaceOnUse' refY='5' refX='4.5' viewBox='0 0 10 10' class='marker flowchart-v2' id='mermaid-0_flowchart-v2-pointStart'%3e%3cpath style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b' class='arrowMarkerPath' d='M 0 5 L 10 10 L 10 0 z'/%3e%3c/marker%3e%3cmarker orient='auto' markerHeight='11' markerWidth='11' markerUnits='userSpaceOnUse' refY='5' refX='11' viewBox='0 0 10 10' class='marker flowchart-v2' id='mermaid-0_flowchart-v2-circleEnd'%3e%3ccircle style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b' class='arrowMarkerPath' r='5' cy='5' cx='5'/%3e%3c/marker%3e%3cmarker orient='auto' markerHeight='11' markerWidth='11' markerUnits='userSpaceOnUse' refY='5' refX='-1' viewBox='0 0 10 10' class='marker flowchart-v2' id='mermaid-0_flowchart-v2-circleStart'%3e%3ccircle style='stroke-width: 1%3b stroke-dasharray: 1%2c 0%3b' class='arrowMarkerPath' r='5' cy='5' cx='5'/%3e%3c/marker%3e%3cmarker orient='auto' markerHeight='11' markerWidth='11' markerUnits='userSpaceOnUse' refY='5.2' refX='12' viewBox='0 0 11 11' class='marker cross flowchart-v2' id='mermaid-0_flowchart-v2-crossEnd'%3e%3cpath style='stroke-width: 2%3b stroke-dasharray: 1%2c 0%3b' class='arrowMarkerPath' d='M 1%2c1 l 9%2c9 M 10%2c1 l -9%2c9'/%3e%3c/marker%3e%3cmarker orient='auto' markerHeight='11' markerWidth='11' markerUnits='userSpaceOnUse' refY='5.2' refX='-1' viewBox='0 0 11 11' class='marker cross flowchart-v2' id='mermaid-0_flowchart-v2-crossStart'%3e%3cpath style='stroke-width: 2%3b stroke-dasharray: 1%2c 0%3b' class='arrowMarkerPath' d='M 1%2c1 l 9%2c9 M 10%2c1 l -9%2c9'/%3e%3c/marker%3e%3cg class='root'%3e%3cg class='clusters'/%3e%3cg class='edgePaths'%3e%3cpath marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)' style='' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' id='L_A_B_0' d='M241.406%2c111L245.573%2c111C249.74%2c111%2c258.073%2c111%2c265.74%2c111C273.406%2c111%2c280.406%2c111%2c283.906%2c111L287.406%2c111'/%3e%3cpath marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)' style='' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' id='L_B_C_1' d='M551.406%2c111L555.573%2c111C559.74%2c111%2c568.073%2c111%2c575.74%2c111C583.406%2c111%2c590.406%2c111%2c593.906%2c111L597.406%2c111'/%3e%3cpath marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)' style='' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' id='L_C_D_2' d='M825.859%2c72L835.951%2c67.833C846.042%2c63.667%2c866.224%2c55.333%2c879.815%2c51.167C893.406%2c47%2c900.406%2c47%2c903.906%2c47L907.406%2c47'/%3e%3cpath marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)' style='' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' id='L_C_H_3' d='M825.859%2c150L835.951%2c154.167C846.042%2c158.333%2c866.224%2c166.667%2c879.815%2c170.833C893.406%2c175%2c900.406%2c175%2c903.906%2c175L907.406%2c175'/%3e%3cpath marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)' style='' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' id='L_D_E_4' d='M1171.406%2c47L1175.573%2c47C1179.74%2c47%2c1188.073%2c47%2c1195.74%2c47C1203.406%2c47%2c1210.406%2c47%2c1213.906%2c47L1217.406%2c47'/%3e%3cpath marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)' style='' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' id='L_E_F_5' d='M1481.406%2c47L1485.573%2c47C1489.74%2c47%2c1498.073%2c47%2c1505.74%2c47C1513.406%2c47%2c1520.406%2c47%2c1523.906%2c47L1527.406%2c47'/%3e%3cpath marker-end='url(%23mermaid-0_flowchart-v2-pointEnd)' style='' class='edge-thickness-normal edge-pattern-solid edge-thickness-normal edge-pattern-solid flowchart-link' id='L_F_G_6' d='M1761.281%2c47L1765.448%2c47C1769.615%2c47%2c1777.948%2c47%2c1785.615%2c47C1793.281%2c47%2c1800.281%2c47%2c1803.781%2c47L1807.281%2c47'/%3e%3c/g%3e%3cg class='edgeLabels'%3e%3cg class='edgeLabel'%3e%3cg transform='translate(0%2c 0)' class='label'%3e%3cforeignObject height='0' width='0'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' class='labelBkg' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg transform='translate(0%2c 0)' class='label'%3e%3cforeignObject height='0' width='0'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' class='labelBkg' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg transform='translate(0%2c 0)' class='label'%3e%3cforeignObject height='0' width='0'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' class='labelBkg' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg transform='translate(0%2c 0)' class='label'%3e%3cforeignObject height='0' width='0'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' class='labelBkg' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg transform='translate(0%2c 0)' class='label'%3e%3cforeignObject height='0' width='0'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' class='labelBkg' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg transform='translate(0%2c 0)' class='label'%3e%3cforeignObject height='0' width='0'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' class='labelBkg' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg class='edgeLabel'%3e%3cg transform='translate(0%2c 0)' class='label'%3e%3cforeignObject height='0' width='0'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' class='labelBkg' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='edgeLabel'%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3c/g%3e%3cg class='nodes'%3e%3cg transform='translate(124.703125%2c 111)' id='flowchart-A-0' class='node default'%3e%3crect height='54' width='233.40625' y='-27' x='-116.703125' style='' class='basic label-container'/%3e%3cg transform='translate(-86.703125%2c -12)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='24' width='173.40625'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3eHuman moves controller%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg transform='translate(421.40625%2c 111)' id='flowchart-B-1' class='node default'%3e%3crect height='102' width='260' y='-51' x='-130' style='' class='basic label-container'/%3e%3cg transform='translate(-100%2c -36)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='72' width='200'%3e%3cdiv style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3e%c2%a71 Tracking error %e2%86%92 gain %e2%86%92 saturation %e2%86%92 cartesian_velocity%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg transform='translate(731.40625%2c 111)' id='flowchart-C-3' class='node default'%3e%3crect height='78' width='260' y='-39' x='-130' style='' class='basic label-container'/%3e%3cg transform='translate(-100%2c -24)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='48' width='200'%3e%3cdiv style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3e%c2%a72 Scale Cartesian command%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg transform='translate(1041.40625%2c 47)' id='flowchart-D-5' class='node default'%3e%3crect height='78' width='260' y='-39' x='-130' style='' class='basic label-container'/%3e%3cg transform='translate(-100%2c -24)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='48' width='200'%3e%3cdiv style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3e%c2%a73 Differential IK %e2%86%92 joint_velocity%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg transform='translate(1041.40625%2c 175)' id='flowchart-H-7' class='node default'%3e%3crect height='78' width='260' y='-39' x='-130' style='' class='basic label-container'/%3e%3cg transform='translate(-100%2c -24)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='48' width='200'%3e%3cdiv style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3e%c2%a72 Record Cartesian target %e2%86%92 cartesian_position%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg transform='translate(1351.40625%2c 47)' id='flowchart-E-9' class='node default'%3e%3crect height='78' width='260' y='-39' x='-130' style='' class='basic label-container'/%3e%3cg transform='translate(-100%2c -24)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='48' width='200'%3e%3cdiv style='display: table%3b white-space: break-spaces%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b width: 200px%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3e%c2%a74 Resolve joint target %e2%86%92 joint_position%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg transform='translate(1646.34375%2c 47)' id='flowchart-F-11' class='node default'%3e%3crect height='54' width='229.875' y='-27' x='-114.9375' style='' class='basic label-container'/%3e%3cg transform='translate(-84.9375%2c -12)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='24' width='169.875'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3eLow-level torque control%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3cg transform='translate(1905.0703125%2c 47)' id='flowchart-G-13' class='node default'%3e%3crect height='54' width='187.578125' y='-27' x='-93.7890625' style='' class='basic label-container'/%3e%3cg transform='translate(-63.7890625%2c -12)' style='' class='label'%3e%3crect/%3e%3cforeignObject height='24' width='127.578125'%3e%3cdiv style='display: table-cell%3b white-space: nowrap%3b line-height: 1.5%3b max-width: 200px%3b text-align: center%3b' xmlns='http://www.w3.org/1999/xhtml'%3e%3cspan class='nodeLabel'%3e%3cp%3eRobot's next state%3c/p%3e%3c/span%3e%3c/div%3e%3c/foreignObject%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/g%3e%3c/svg%3e)
Let me introduce some symbols that might be used in following section.
| Stage | Symbol |
|---|---|
| Mapped controller pose | |
| Normalized arm and gripper commands | |
| Scaled Cartesian command | |
| Recorded Cartesian target | |
| Differential IK output, normalized | |
| Joint and gripper targets | |
| Low-level arm control | |
| Next observed flange pose |
1. The Human-VR Outer Loop: cartesian_velocity
The cartesian_velocity action can be defined as:
The fun fact is that the cartesian_velocity has nothing to do with standard physical velocity (like m/s or rad/s). What?🤯 Yes, you read that right. The literal “velocity” label tripped me up at first, too.
So what it is?🧐 Let’s break it down.
TipThe big picture is: the recorded action
action_dict/cartesian_velocityhas two parts:
- Indices 0-2 control translation.
- Indices 3-5 control rotation.
The gripper has a separate scalar command.
📌 Tracking error
DROID’s VR controller uses proportional feedback. When we start teleoperation, we reset the motion reference and store the controller pose and robot pose. Call this reference step 📸.
For translation, positions are measured in meters, so each displacement below is also in meters:
RemarkIntuitively,
- measures the displacement(translation) of the Oculus Quest 2 controller from the latched pose.
- measures the translation between the current end-effector frame and when it was at the time .
The translation error, also in meters, is
ExampleIf your hand has moved forward by 0.10 m and the robot has moved forward by 0.06 m, the translation error is 0.04 m.
For rotation, we have a similar concept. However, rather than simple subtraction, we need relative rotations:
DROID forms the rotation error and converts it to Euler coordinates in radians:
RemarkThe code computes these products with quaternions, which is equivalent to the rotation-matrix calculation above. Here, refers to X-Y-Z fixed angles (SciPy’s lowercase
xyzconvention). This is an Euler representation of the relative rotation, not a rotation-vector logarithm, therefore it still has Euler-angle branch cuts and singularities.
📌 Gains
Recall that we usually need to set and for a PD controller. The same logic applies to DROID error tracking. With the current defaults, DROID scales the errors as follows:
RemarkHere, the equations follow the code’s numerical convention: contains position errors expressed in meters, and contains Euler-angle errors expressed in radians.
📌 The norm
Translation and rotation are independently rescaled so that each Euclidean norm is at most 1:
ExampleSuppose . Its norm is , so DROID divides the vector by 1.5. The result is : the direction stays the same, but the magnitude is capped.
📌 Scalar clipping
The gripper command is clipped to the interval :
The arm command is
This is action_dict/cartesian_velocity, while is action_dict/gripper_velocity.
cartesian_velocityis a normalized commandAs I reminded you before, the field name can be misleading. These values are gain-scaled, saturated tracking errors. They do not directly measure how fast the Oculus controller or robot is moving. (i.e., it is NOT a physical velocity in standard SI).
2. Scaling and Recording the Target: cartesian_position
The outer loop gave us a normalized cartesian_velocity. Before this signal ever reaches a joint, DROID scales it back into physical units and uses it to construct an absolute pose which is recorded alongside everything else as action_dict/cartesian_position.
RemarkThis construction, and the differential IK that follows it, is split between the IK wrapper and
FrankaRobot.create_action_dict.
0️⃣ The cartesian_velocity
Recall that the cartesian_velocity is
1️⃣ Scale the Cartesian command
The wrapper repeats the separate limits on translation and rotation, then applies the default scales
For the already bounded commands from Section 1, this gives
TipNow we finally feel a connection to the physical world again. The dimensionless “maximum” value of
1in translation now becomes “0.075m / control step”.
RemarkThese scales define the increments used to construct a Cartesian target on each update. They do not guarantee that the robot will move to the exact target during the next 15 Hz interval.
2️⃣ Construct the recorded Cartesian target
Let the subscript mark the robot state read when the command is resolved. DROID constructs
Here, converts extrinsic xyz Euler angles to a rotation matrix. Translation is added in the base frame, and the incremental rotation is composed on the left.
The translation and rotation together define the action_dict/cartesian_position.
The reference state is read at command timeA single control cycle performs two separate robot state reads:
- : the saved observation (read early, before computing the action).
- : the fresh reference (read later by
create_action_dict).DROID constructs the target as . Why use the later read? 🤔 My guess is to ensure the intended motion is “fully expressed.”
Because the arm moves between reads, anchoring the command to the outdated would shortchange the displacement. For example: if m, the robot drifts to m by command time, and the desired delta m. A target of m (based on ) only yields m of actual physical movement. Adding the delta directly to the fresh ensures the full m offset executes.
3. Differential IK: joint_velocity
Alright alright alright, we see the word “velocity” again in joint_velocity. Does it also lack a standard physical meaning? Is it not in SI units?
Correct, joint_velocity is also normalized! :- )
DROID uses dm_robotics’s Cartesian6dVelocityEffector for differential IK, where the input and output can be viewed as
where
- input includes
- : the current joint position
- : the current joint velocity
- : the desired twist
- output includes
- : the desired joint velocity
Let denote the DROID wrapper’s calculation. It treats the measured joint positions , measured velocities , and the scaled 6-vector as input. The wrapper computes
where is the default joint-step scale.
RemarkA few things are worth mentioned⭐️:
- The scaled 6-vector (
cartesian_velocity) is not rigorously the twist we know from robotics textbook like Modern Robotics: Mechanics, Planning, and Control. It’s more of a “Cartesian increment”.- Vice versa, the
dm_roboticssolver’s numerical output is treated as a joint increment in radians.
And ladies and gentlemen, the normalized result is saved as action_dict/joint_velocity.
📌Where does the “normalized” come from?
The joint_velocity is normalized such that
Looking at the equation , this bounded range might not be obvious. It works because DROID sets the same numerical limit for all 7 joints at IK configuration:
self.relative_max_joint_delta = np.array([0.2, 0.2, 0.2, 0.2, 0.2, 0.2, 0.2])This array is passed to Cartesian6dVelocityEffector. Because the effector intrinsically bounds its own output. The joint increment produced by is already constrained to [-0.2, 0.2]rad. Therefore
4. Resolving the Joint Target: joint_position
DROID converts the joint_velocity command into an increment using for every joint, applies infinity norm saturation if needed, and adds it to the reference configuration:
From last section, we know that is already normalized such that . Therefore, the preceding equation could be simplified as:
TipIntuitively, it caps each joint increment is at most in magnitude. Note that this operation alone does not enforce the physical joint limits of the robot.
IK(cartesian_position)does NOT guaranteejoint_positionAs you might suspect, running pose-based IK on the recorded
cartesian_position, even when seeded with the observed joint configuration, is not guaranteed to reproduce the recordedjoint_position. Reproduction requires following DROID’s differential-IK and joint target construction path.
5. The Common Pitfall
We now have the joint target . They are sent to their low-level controllers, but the robot does not reach them instantly.
The arm controller produces motor torques , while the physical response depends on inertia, gravity, friction, contact, latency, etc. The DROID outer loop targets 15 Hz, while the Franka hardware client is configured for 1 kHz.
We therefore cannot assume
Commanded action versus observed motionYou generally cannot recover the commanded action by subtracting two consecutive observations. In particular, the expression
measures a scaled observed displacement. It is NOT generally equal to . They may coincide in a special case, but this is not a reliable way to reconstruct actions.
Where Do VLA Models Plug In?
A learned policy takes observations and a language instruction , then predicts an action chunk. The training target determines which part of the control pipeline it learns to imitate.
RemarkA hat marks a policy prediction. I write for the action intended for step , predicted using information available at step . See also Understanding Action Chunking with Flow Matching for how action chunk is used in robot learning.
📌 OpenPI -DROID: joint velocity
The original pi05_droid checkpoint’s deployment path uses normalized joint velocity commands and absolute gripper position targets:
- In training: the arm prediction corresponds to the output of differential IK, before the joint target resolver.
- In deployment, DROID converts that normalized joint command into a desired absolute joint position using a fresh robot state.
📌 OpenPI -DROID: joint position
There are 2pi05_droidcheckpoints, not 1It’s easy to miss this🙃: Physical Intelligence ships
pi05_droid(joint velocity) and a laterpi05_droid_jointpos(joint position), introduced alongside 📄PolaRiS: Scalable Real-to-Sim Evaluations for Generalist Robot Policies. The velocity checkpoint is the widely-cited default while the position checkpoint is the one the training guide recommends for simulation-friendly training. This is also why the RLDS loader defaults to joint position targets.
For the joint position variant, the policy output transform converts predicted joint deltas into absolute targets, so the deployed action is
Its arm output corresponds to the joint position target after DROID’s joint target resolver and can be executed with action_space="joint_position", without differential IK or the normalized joint command rescaling. The PolaRiS checkpoint list lists this base checkpoint separately from pi05_droid_jointpos_polaris, which adds further training on a mixture of simulated and DROID data.
📌 NVIDIA GR00T N1.7-DROID
Unlike OpenPI, GR00T’s DROID configuration does something challenging: it learns to predict both the end-effector pose(cartesian_position) AND the joint angles (joint_position) simultaneously, alongside an absolute gripper target.
The Rollout Trap: Cartesian and Joint targets are NOT interchangeableIt is incredibly easy to misunderstand this during deployment. You might assume that GR00T’s predicted
cartesian_positionandjoint_positionare geometrically identical. Meaning, you could just run inverse kinematics on the predicted Cartesian pose to get the exact predicted joint angles.They are not. As explained earlier, DROID processes these two spaces through entirely distinct clipping and differential IK paths. Because GR00T predicts both of these separately derived targets, you must be extremely careful during rollout. You have to explicitly decide which action space drives your low-level controller, and you cannot assume the two predicted outputs will perfectly mirror each other.
Data formatting notes
- Relative actions: GR00T learns these as relative targets (relative to the latest observation in the action chunk). See Action Representations.
- Dataset source: GR00T uses the LeRobot format, not raw RLDS. The DROID-to-LeRobot converter explicitly copies
action_dict/cartesian_positionandaction_dict/joint_positioninto separate fields to allow this dual-prediction setup.
Which Settings Must Match Your Action Space?
💬Question
I want to collect DROID-like data with your own controller. Do I have to copy , , , , and exactly🧐?
🗣Answer
It depends entirely on which field your model learns to predict.
DROID-trained checkpoints are the “free lunch”. In order to use them, we should align the generation and meaning of our chosen action labels with DROID. Here we focus on data collection through DROID-style Cartesian teleoperation and only the 5 parameters .
WarningUsing exact parameters does not guarantee you will get 100% out of the pre-trained checkpoint, but ignoring them almost guarantees you will struggle to use them effectively.
| Recorded action field | |||||
|---|---|---|---|---|---|
cartesian_velocity | ✅ | ✅ | ✅ | ✅ | ❌ |
cartesian_position | ✅ | ✅ | ✅ | ✅ | ❌ |
joint_velocity | ✅ | ✅ | ✅ | ✅ | ✅ |
joint_position | ✅ | ✅ | ✅ | ✅ | ✅ |